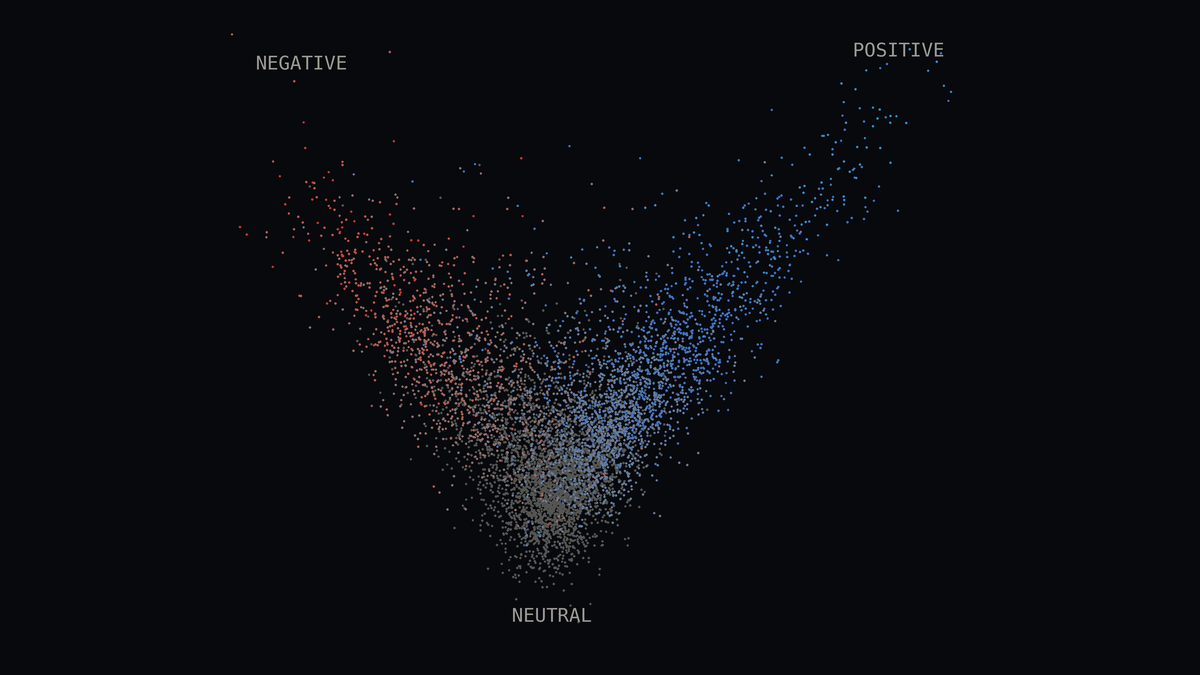
Late September, at TeknSEO in Toulouse, I spent 80 minutes explaining that a small model trained on your own data often does better, faster and cheaper than a big model you ask questions to. Early November, I read Dejan’s post about his seven-level sentiment classifier. Three days later, an open dataset and two models in six languages were online. And you can pitch in: I’m building a hand-labeled reference set (a “gold” dataset), and your help would be very welcome (this way). Here is how it came together.
Read more Seven shades of sentiment, six languages and three days of tinkering